01
Prompts change. Quality drifts.
Prompt changes ship unmeasured.
AI AGENT QUALITY PLATFORM
BETTER AGENTS START WITH BETTER EVIDENCE.
Tagnos is the quality platform for AI agents: annotate your data, evaluate your agents, package them as skills, and publish them. Built on the Claude API (the interface used to send requests to Claude), designed for teams without a data science department.
$ tagnos eval --compare v3 v4
✓ Human-calibrated judge
✓ Task completion improved
! Policy regression detected
→ Review before publishing
FROM HUMAN KNOWLEDGE TO PROVEN AGENTS
Founded by two PhDs in AI and natural language processing · 12+ years of production AI · Built on the Claude API
Built on the Claude API01 / THE PROBLEM
A convincing answer isn’t always a correct one. Give your team a way to tell the difference.
Prompt changes ship unmeasured.
Manual annotation is slow, costly and not reproducible.
Errors are discovered in production — by your customers.
Every new agent starts from scratch.
02 / THE LOOP
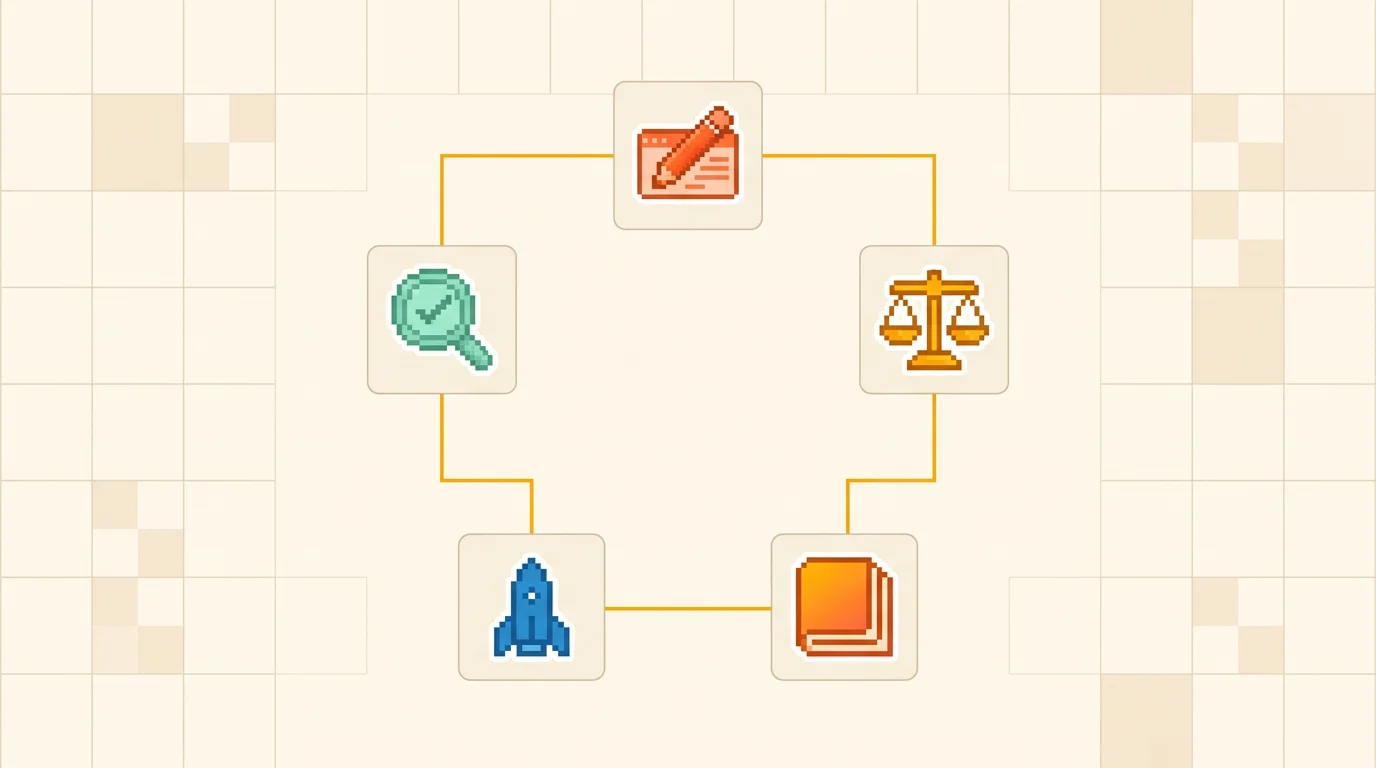
A continuous quality loop. Each step makes the next one stronger.
Turn expert knowledge into trusted labels.
Measure your agents against human standards.
Make validated knowledge reusable.
Share skills and plugins; publish agents to the upcoming Agent-to-Agent (A2A) marketplace, where agents can talk to each other.
Bring new evidence back into the loop.
PUBLISH. LEARN. GO AROUND AGAIN.
03 / THE PLATFORM
Benchmark prompts, agent versions and agents against each other on your own human-validated ground truth — the examples your experts have checked.
01 / HUMAN + MACHINE
Claude annotates your data first. Your experts validate, correct and turn it into a reliable foundation for better agents.
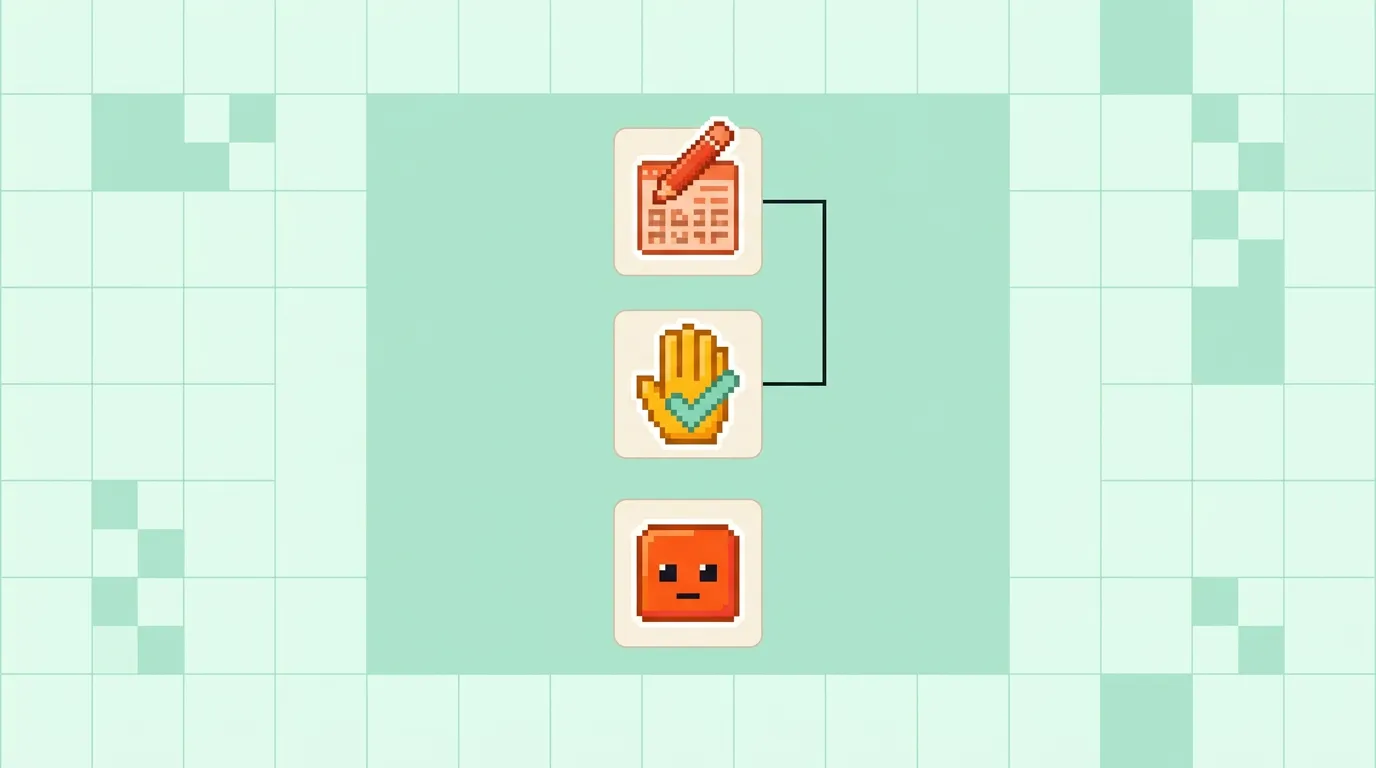
02 / SHARED STANDARDS
Build a visual annotation schema, bring your experts together and measure where their judgments agree.
03 / EVIDENCE OVER INSTINCT
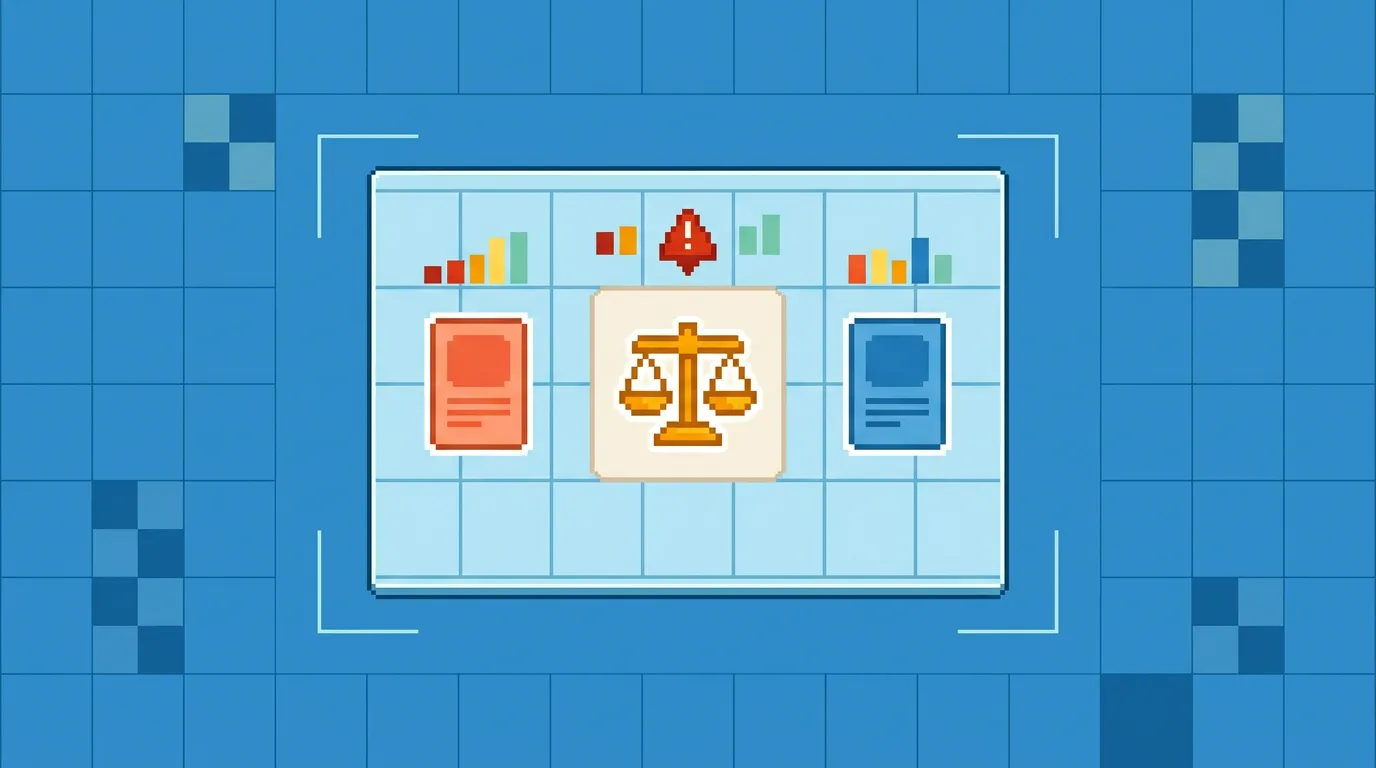
Benchmark prompts, agent versions and agents against each other on your own human-validated ground truth. Calibrate an AI model used as a judge on human labels and detect regressions before your next release.
04 / KNOWLEDGE THAT COMPOUNDS
Author Claude Skills and Plugins from validated data. Package your team’s know-how as reusable agent capabilities.
05 / AGENTS, CONNECTED
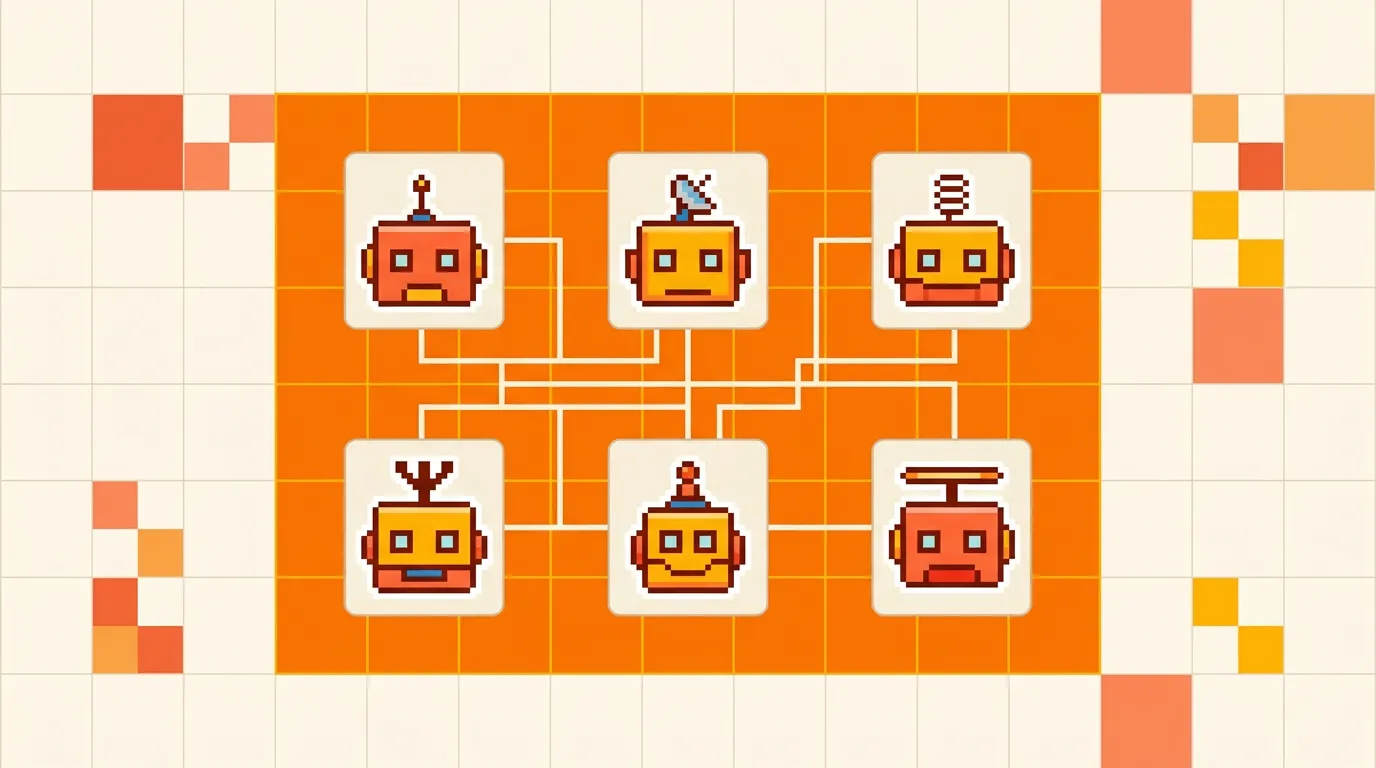
The upcoming marketplace will let you publish, discover and connect agents through the Agent-to-Agent protocol. Make proven capabilities available to other teams.
THE LOOP / PACKAGE & PUBLISH
Carry the evidence forward. Skills, plugins and connected agents extend the same quality loop.
Turn validated data and evaluation results into tested, documented Claude skills and plugins. Keep reusable capabilities linked to the evidence behind them.
Publish, discover and connect agents that talk to each other via the Agent-to-Agent protocol. Bring their results back into the quality loop.
04 / PROOF, NOT GUESSWORK
Benchmark prompts, agent versions and agents against each other on your own human-validated ground truth. A gain in one dimension should never hide a step backwards in another.
PROMPT → DATASET → JUDGE → RESULT
Support agent / release comparison
pp = percentage points: the difference between two percentages.
Policy adherence dropped. Review the failed cases before publishing.
Illustrative results only. These are not Tagnos performance claims.
05 / BUILT FOR YOUR TEAM
You don’t need a data science department. You need a clear view of what your agents can do.
An AI quality manager without hiring.
Bring structure to agent quality with the people and knowledge you already have.
Prove each release beats the last.
Make agent quality part of your release process, with clear comparisons and reproducible tests.
Make your know-how reusable.
Package your expertise as skills and agents that other teams can discover and connect.
06 / THE TAGNOS STANDARD
Evaluate changes against a consistent benchmark before they reach customers.
Expert judgment sets the standard. AI helps you apply it at scale.
Built on the Claude API, with skills and plugins; Model Context Protocol (MCP) connects AI to tools and data, and Agent-to-Agent (A2A) connects agents to each other.
Follow a result back to its prompt, dataset, human labels and evaluation.
07 / HOW IT WORKS
Start with the agent you have. Build the evidence you need.
Bring a dataset or test an existing agent through its external interface.
Let Claude suggest labels, then have your experts validate the standard.
Run calibrated evaluations and see exactly where quality changes.
Package your knowledge, publish your agent and keep measuring.
agent: support-triage
labels: human-validated
judge: claude
compare: [prompt-v3, prompt-v4]
on_regression: review
next: re-measure
08 / GOOD QUESTIONS
No. Tagnos is built for product and business teams. AI-assisted annotation, guided evaluation and clear comparisons help your existing experts set the quality standard.
Tagnos is built on Anthropic’s Claude API. Claude powers pre-annotation and evaluation, with human labels used to calibrate judgment.
Yes. Black-box external testing lets you evaluate an existing agent with minimal integration, through the interface it already exposes.
No. Your data is used only to run your annotations and evaluations. Tagnos is built on Anthropic’s commercial Claude API, and we do not use your data to train models. Contact us for our full data processing terms.
YOUR NEXT RELEASE DESERVES EVIDENCE.
Get an introduction to Tagnos. Bring your agent, your questions and your definition of good.
Tell us what you’re building. We’ll walk through a quality loop together.
LET’S TALK QUALITY
Email us for early access or a product demo. Tell us about your agent and what you want to measure.
Email the Tagnos teamcontact@tagnos.app